The cloud is no longer just about moving servers from your data centre to someone else's. Today, cloud platform engineering is about building intelligent, automated infrastructure that scales on demand, costs only what you use, and recovers from failures without human intervention.
Nimaisoft brings deep hands-on expertise across AWS, Azure, and Google Cloud. We help startups build their first scalable architecture and help established enterprises modernise legacy infrastructure without disrupting ongoing operations.
Cloud-native applications are designed from the ground up to take full advantage of cloud infrastructure — they are distributed, containerised, automatically scalable, and highly available. Unlike traditional applications that were simply "lifted and shifted" to the cloud, cloud-native apps are built for it.
We build cloud-native applications using microservices architectures, containers, and managed cloud services. Every component is designed to scale independently, fail gracefully, and deploy continuously — so your application stays fast and available even as your user base grows.
Our cloud-native stack:
Building a SaaS product requires a fundamentally different architecture from building a single-tenant application. You need multi-tenancy, subscription management, usage metering, role-based access, and the ability to onboard hundreds of customers without custom deployments for each.
We have built SaaS platforms across fintech, edtech, healthcare, and enterprise software domains. We help you design the right multi-tenancy model (shared database, separate schemas, or separate instances), implement subscription and billing flows, and build the admin dashboards your operations team needs to manage customers at scale.
Many businesses are still running critical workloads on on-premise servers or ageing cloud setups that were built before best practices matured. These systems are expensive to maintain, difficult to scale, and vulnerable to outages.
We assess your current infrastructure, identify migration risks, and execute structured cloud migrations using proven patterns — re-host, re-platform, or re-architect — depending on what makes business sense. We also specialise in breaking apart monolithic applications into microservices as part of a modernisation programme.
Our migration methodology:
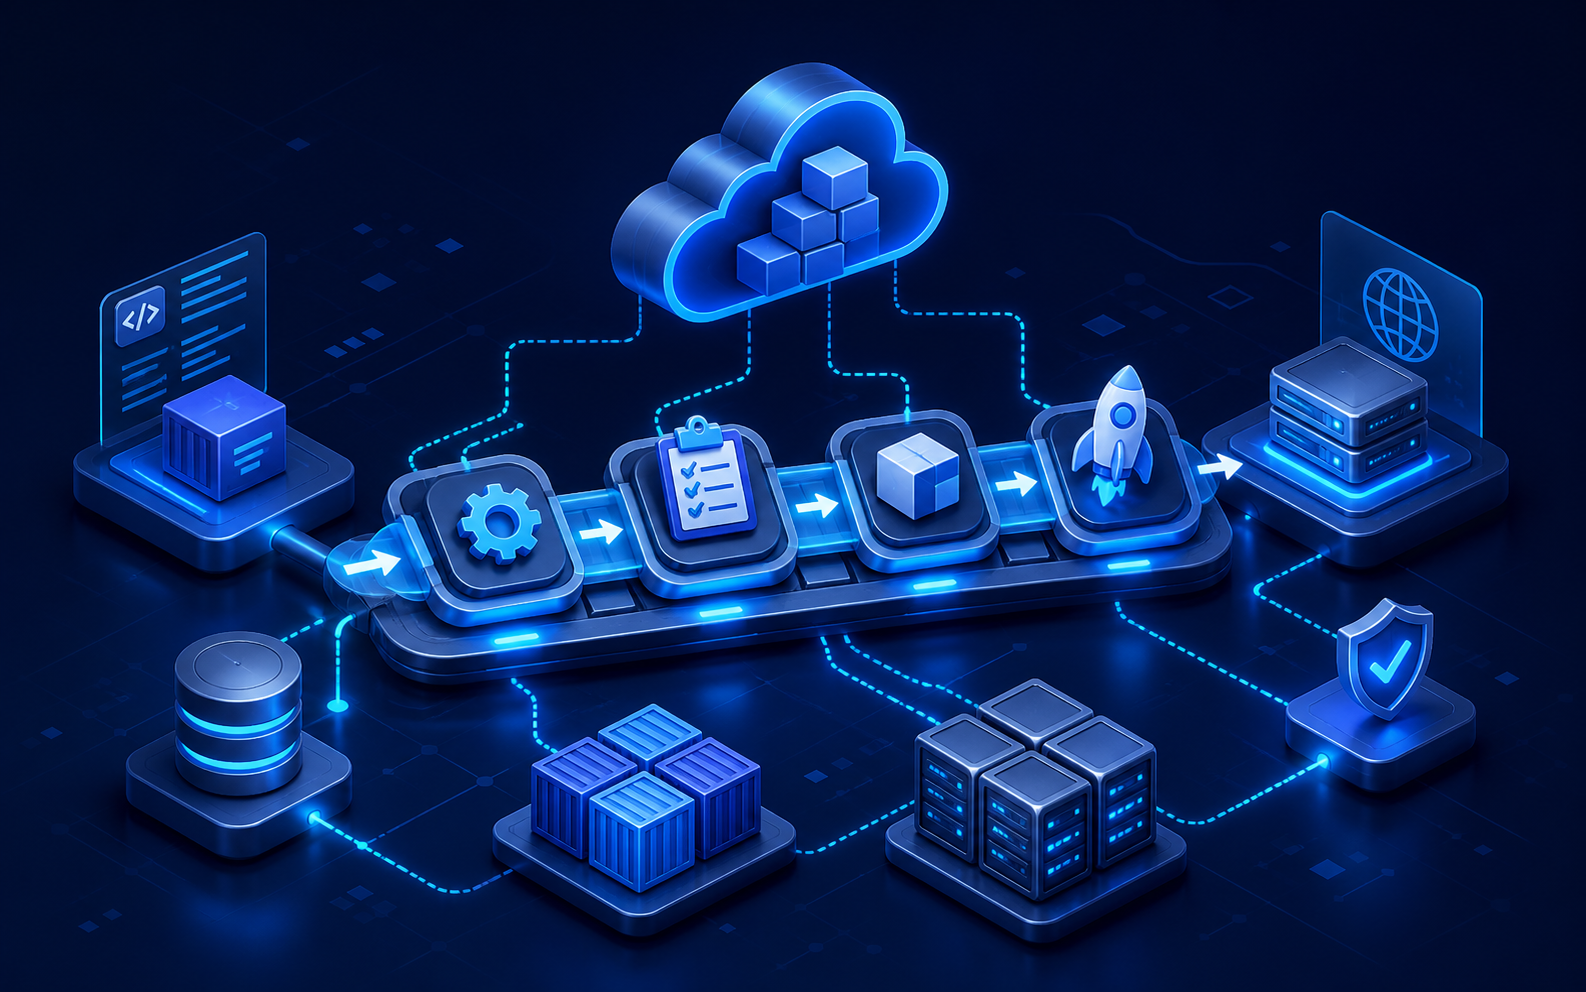
DevOps is the practice of automating everything between writing code and running it in production. A well-built CI/CD pipeline means developers can ship features in hours instead of weeks, with confidence that every change has been tested, reviewed, and deployed safely.
We implement end-to-end DevOps pipelines using GitHub Actions, GitLab CI, and Azure DevOps. Every pipeline includes automated testing, security scanning, container image building, and deployment — so your team ships faster without trading off quality.
What we set up:
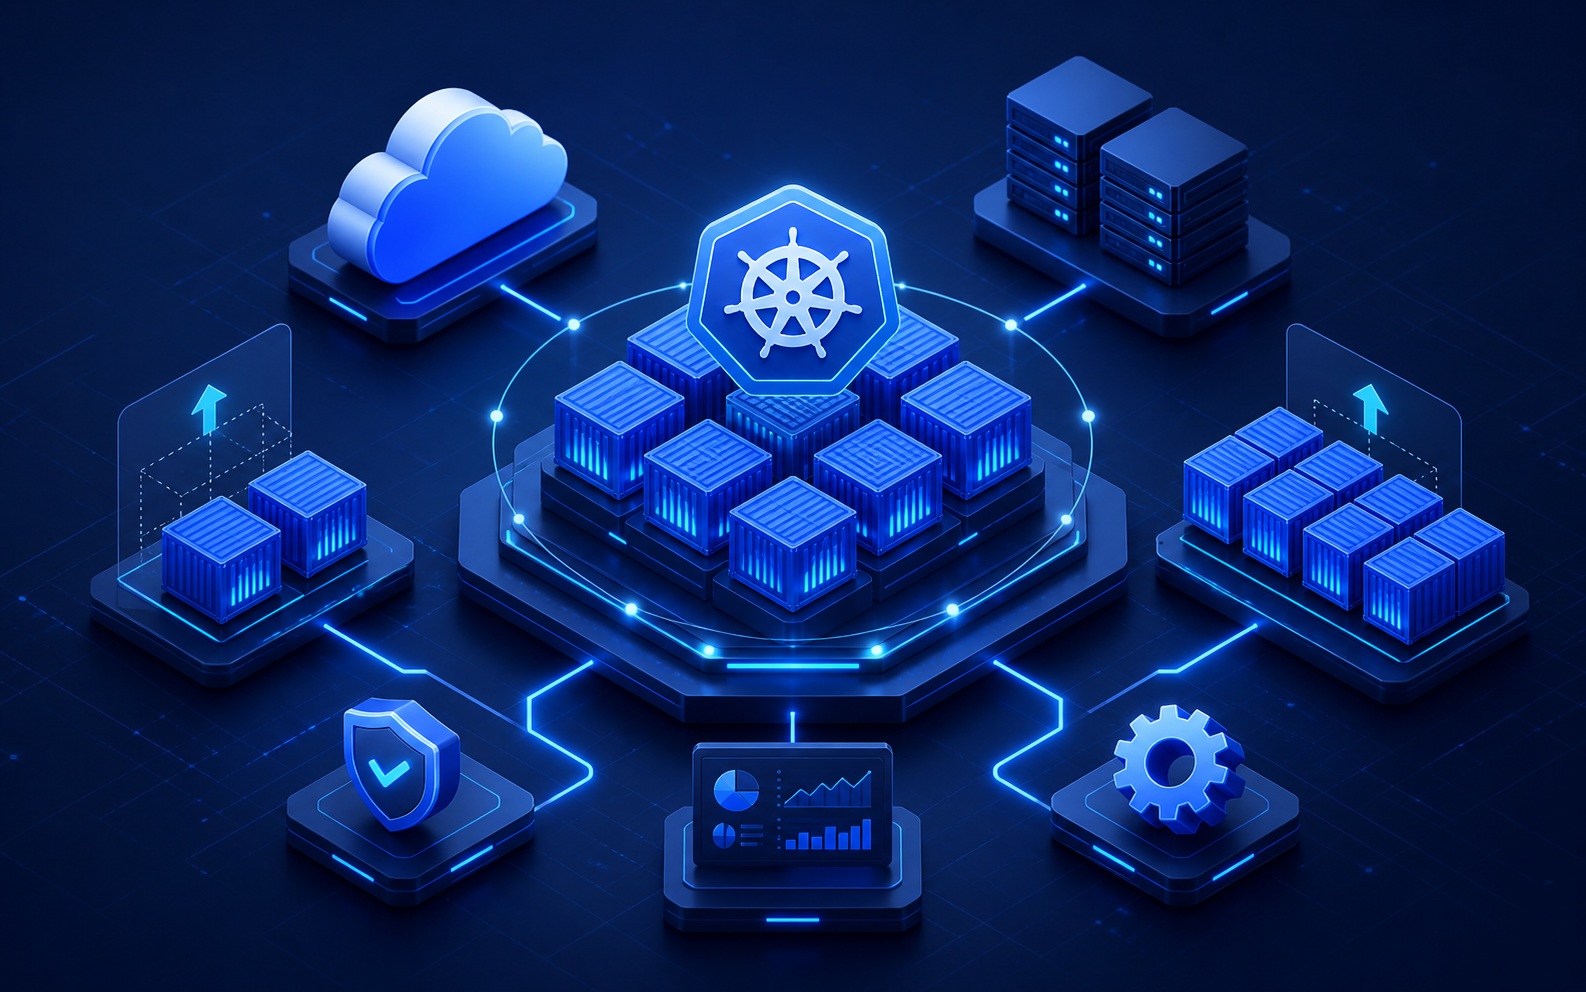
Kubernetes has become the standard platform for running containerised workloads in production. But Kubernetes is complex — misconfigured clusters lead to outages, security vulnerabilities, and spiralling costs. Getting it right from the start matters.
We design, deploy, and manage Kubernetes clusters on AWS EKS, Azure AKS, and Google GKE. We set up proper namespace isolation, resource quotas, network policies, autoscaling, and pod security standards so your cluster is production-ready and secure from day one.
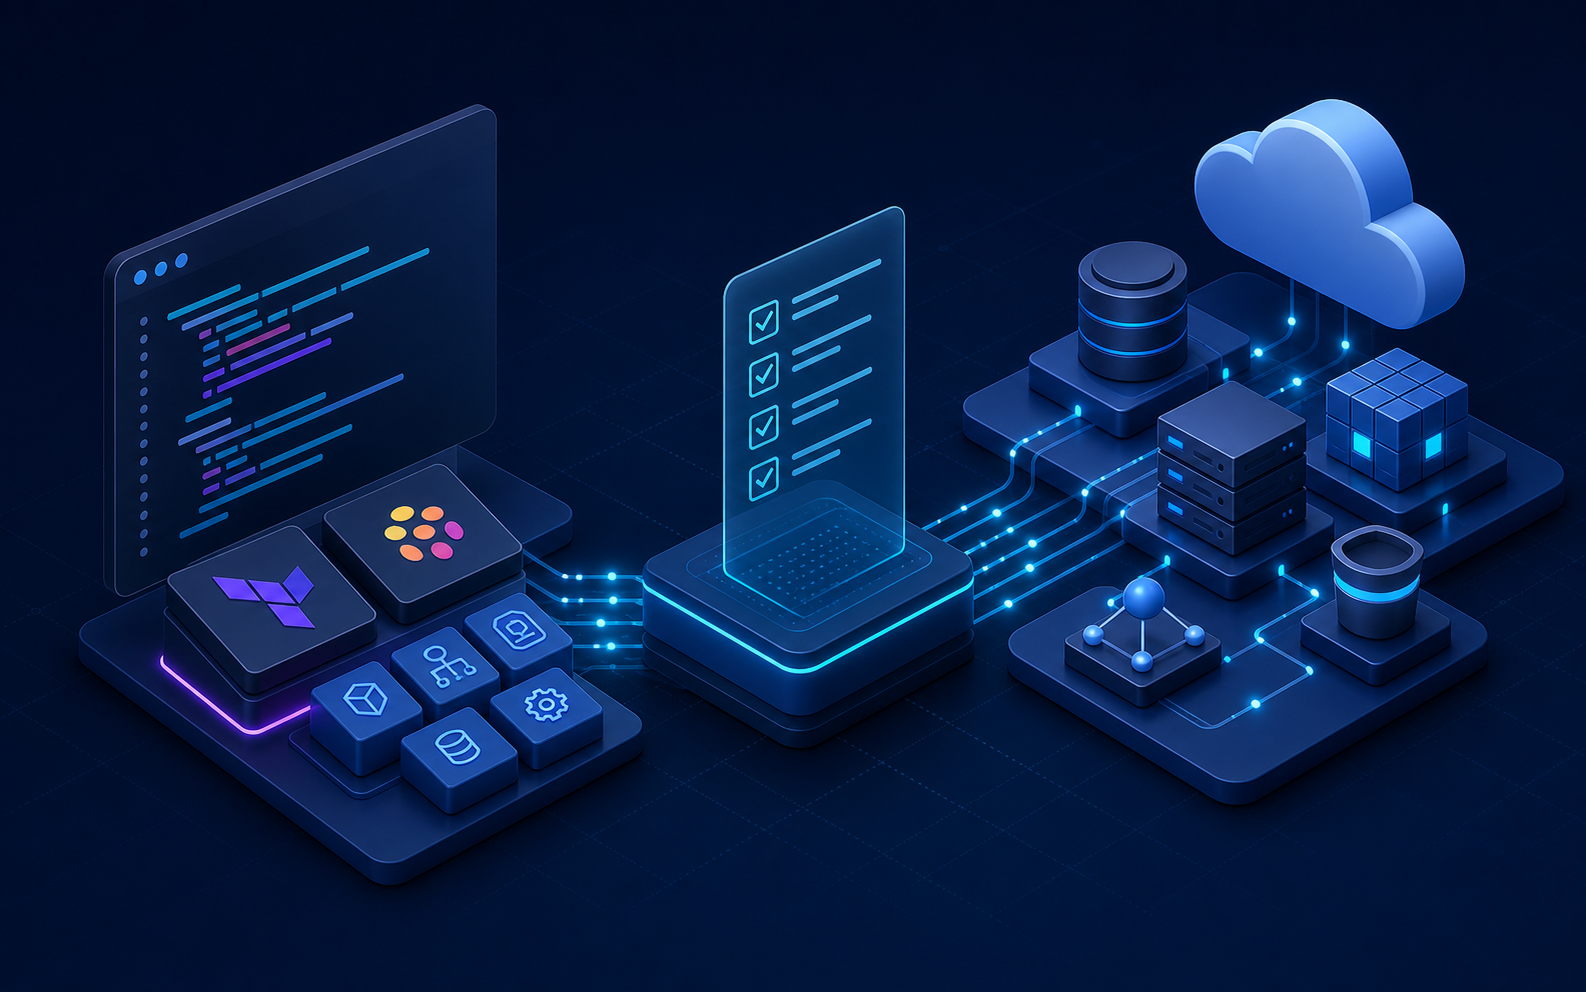
Infrastructure as Code means your servers, networks, databases, and cloud services are defined in code — version-controlled, reviewable, and reproducible. When something goes wrong, you can rebuild your entire infrastructure in minutes. When you need a new environment, you clone it with a single command.
We write and maintain Terraform and Pulumi codebases that describe your complete cloud infrastructure. We organise code into reusable modules, implement proper state management with remote backends, and integrate IaC into your CI/CD pipeline so infrastructure changes go through the same review process as application code.
Serverless computing lets you run code without managing servers. You pay only when your code runs, it scales automatically to any load, and you eliminate the overhead of server management entirely. Combined with event-driven design, serverless architectures are highly scalable and cost-efficient.
We design and build serverless systems using AWS Lambda, Azure Functions, and Google Cloud Run. We connect them with event buses (EventBridge, Pub/Sub, Kafka) to create decoupled, resilient pipelines that process millions of events with no manual intervention.
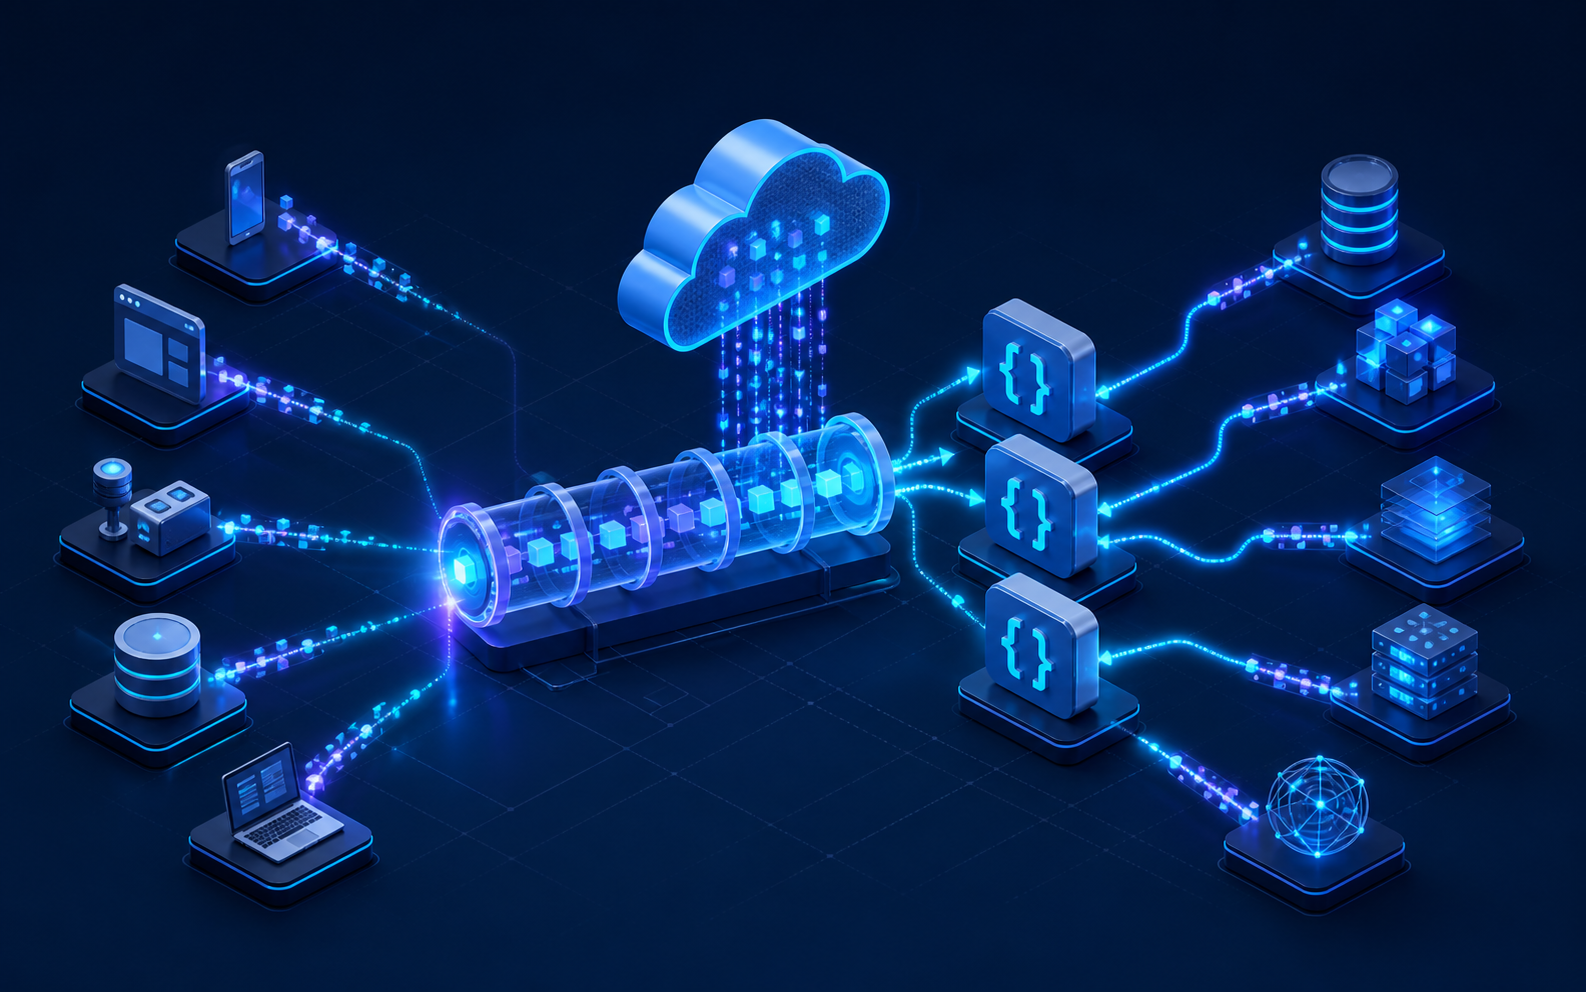
Microservices decompose a large application into small, independent services that each handle a specific business capability. This makes it possible to deploy, scale, and update individual services without affecting the rest of the system.
We design microservice boundaries using Domain-Driven Design principles, implement inter-service communication using REST, gRPC, and event-driven messaging, and deploy an API gateway layer (Kong, AWS API Gateway, or Azure APIM) to manage routing, authentication, rate limiting, and observability for all incoming traffic.
You cannot manage what you cannot see. Observability — the ability to understand what is happening inside your systems from the outside — is critical for catching problems before they affect users and for diagnosing issues quickly when they do.
We implement the three pillars of observability: metrics, logs, and traces. Using Prometheus, Grafana, OpenTelemetry, and cloud-native monitoring tools, we give your team real-time visibility into every layer of your stack. We also implement alert routing so the right person gets notified when something goes wrong.
Cloud bills have a habit of growing faster than expected. Without active cost management, engineering teams unknowingly leave expensive resources running, choose over-provisioned instance types, and miss significant saving opportunities.
We conduct cloud cost reviews, identify waste, implement tagging strategies for cost attribution, and configure autoscaling and spot instance strategies that can reduce your cloud bill by 30–50% without compromising performance.
Many enterprises need to operate across multiple cloud providers — to avoid vendor lock-in, meet data residency requirements, or combine the best services from different providers. Hybrid cloud extends this further by integrating on-premise infrastructure with public cloud.
We design multi-cloud and hybrid architectures that give you flexibility without creating unmanageable complexity. We implement consistent networking, identity management, and security policies across providers so your teams work in a unified environment regardless of where workloads run.
Site Reliability Engineering (SRE) applies software engineering practices to infrastructure and operations. SRE teams define SLOs (service level objectives), implement error budgets, automate incident response, and continuously improve system reliability.
We offer managed cloud services where our SRE team takes ongoing responsibility for your infrastructure — monitoring, patching, scaling, incident response, and continuous optimisation — so your engineering team can focus entirely on building product.